
GitHub trend signals, in the market-intelligence sense used across strategy teams, are AI-generated early readings of demand, sentiment and momentum, pulled from search behaviour, recommendation patterns and query data before those shifts show up in sales figures. The lead time on buyer-facing trends runs roughly 4 to 12 weeks, which is enough to reposition content, run a pilot or adjust a launch date. The first move is simple: add the signal to a watchlist and cross-check it against a second source before you act on it alone.
TL;DR:
- Signals are most trustworthy when they appear across multiple platforms, show rapid growth in mentions, and include detailed attribute language.
- Investors should prioritize ranking concentration signals for early market share insights, while product teams focus on attribute vocabulary shifts, which indicate unmet demand.
- Proper validation involves cross-platform corroboration, human confirmation, and matching search volume trends before acting on signals.
- Weak signals usually lack breadth, velocity, and attribute depth, and should be treated as noise until they reappear consistently.
- Maintaining a timestamped, cross-validated watchlist helps teams move from early signals to confident business decisions.
Table of Contents
- How do AI-generated trend signals actually work?
- Which signals matter most, and how strong is strong?
- How do you turn a signal into a decision?
- Where do these systems break, and what should you watch for?
- How can you verify a trend signal before acting on it?
- How we actually use these signals day to day
- Putting github trend signals to work with Ontherice
- Sources
How do AI-generated trend signals actually work?
Most platforms, Ontherice included, build these signals from three raw ingredients: what people are asking AI assistants and search engines, how the vocabulary around a product category is shifting, and which options those same assistants recommend most often. None of this comes from a single clean feed. It is scraped, noisy, and full of duplicate or contradictory mentions, which is why the synthesis step (the part that turns raw mentions into a ranked score) matters more than the raw data itself.
A useful way to think about it: the AI layer is not predicting the future so much as noticing that the present has already changed, just not yet in a place your existing dashboards look.
Four categories of signal tend to recur, and each one serves a different job:
- Query emergence — new search or prompt phrasing appearing where it didn't exist before, often the earliest and vaguest signal.
- Attribute vocabulary shifts — the language buyers use to describe what they want changes before the products themselves do, useful for product and content teams.
- Recommendation and ranking concentration — when AI assistants start recommending the same handful of options repeatedly, that's momentum consolidating, relevant to competitive positioning.
- Cross-platform corroboration — the same signal appearing on more than one assistant or index at once, which is the strongest check against noise.
Product teams care most about attribute shifts, because they hint at unmet feature demand. Marketers care about query emergence, since it tells them what to write about now rather than in a quarter. Investors and strategists tend to weight ranking concentration heaviest, because it's the closest proxy to market share forming in real time.
Which signals matter most, and how strong is strong?
Not every blip deserves a meeting. A practical rubric scores each signal on four dimensions before it earns a place on anyone's watchlist:
- Breadth — how many distinct sources or platforms are reporting it.
- Velocity — how fast the mention volume or ranking position is moving, not just where it sits today.
- Depth — whether the signal shows up in detailed, attribute-level language or only in shallow, generic mentions.
- Recommendation shift — whether AI assistants have started actively recommending the item, versus merely mentioning it.
A strong signal scores well on at least three of the four. A new phrase appearing in product queries across two independent AI assistants, gaining ground week over week, and showing up alongside specific feature language, is worth building a watchlist entry for. A single mention on one platform, with no repeat appearance a week later, is noise. Cross-platform incidence, in particular, is the difference between a signal you can defend in a strategy meeting and one you can't.
Statistic to anchor expectations: agentic AI models tracking market movement have shown a genuine ability to identify winners early. In one nine month sample, an AI-ranked top tier of assets outperformed the Russell 1000 by roughly 24 percentage points, with a daily alpha of 0.184% and an annualised Sharpe ratio near 2.43. That's not a claim about GitHub-style signals specifically, but it demonstrates the underlying mechanism, AI models are measurably better at spotting rising leaders than at reliably flagging decline, a point worth remembering when you interpret any ranking.
A weak signal, by contrast, usually fails on breadth or velocity: it appears once, doesn't repeat, and carries no attribute detail. Treat those as background noise until they reappear.
How do you turn a signal into a decision?
Spotting a signal is the easy part. Turning it into a defensible business decision is where most teams stall, and it is genuinely a pipeline problem, not a one-off detection task.
Start with triage, not analysis. Before committing budget, run the signal through three checks:
- Cross-platform AI visibility: does it show up on more than one assistant or index?
- Human corroboration: do sales reps or customer-facing staff recognise the pattern independently?
- Search-volume confirmation: does a tool like Google Trends show a matching, if smaller, uptick?
If two of those three checks pass, move to a rapid experiment rather than a full rollout. For content and marketing, that means a single piece or landing page tested for two to three weeks. For product, it means a scoped pilot with a defined customer segment, measured over four to six weeks, roughly matching the signal's own visibility window. For go-to-market timing, it means a targeted sales play with a small account list before a full campaign commit.
Set your scale-or-shelve rule before you start, not after you see the results. A sensible default: scale if the experiment shows measurable movement in a leading metric (query volume, pilot conversion, or qualified pipeline) within the test window, and shelve if the signal fails to repeat in a second data pull four weeks later.
Pro Tip: Keep a shared watchlist with a signal's first-seen date, its breadth score, and the check-in date for re-validation. Signals that get revisited on a schedule get acted on; ones left in a Slack thread rarely do.
Where do these systems break, and what should you watch for?
AI signal pipelines are, underneath the marketing language, streaming data systems, and they inherit every weakness of that category. Ingest lag, out-of-order events, and schema drift can all quietly degrade a feed without anyone noticing until a ranking looks obviously wrong.
The asymmetry problem compounds this: these models are consistently better at identifying winners than at flagging decline, so treat any "this is falling out of favour" signal with more scepticism than a "this is rising" one.
Sensible mitigations:
- Set explicit freshness thresholds per signal type, and expose that freshness to the reader rather than hiding it.
- Build conservative fallback behaviour for missing or late data, rather than forcing a confident answer from incomplete inputs.
- Require cross-platform confirmation before treating a single-source spike as actionable.
None of this makes the signals useless. It just means the honest pitch is "early and directional," not "certain."
How can you verify a trend signal before acting on it?
Ask any provider, Ontherice included, for the receipts. A platform worth trusting shows its ranking history rather than just today's snapshot, tracks its own prediction accuracy over time, and timestamps every signal card so you can see exactly when it first appeared.
Concrete artefacts worth requesting:
- A timestamped signal history, not just a current score.
- Cross-platform incidence counts, showing how many independent sources corroborate the same trend.
- A visible accuracy or track-record page rather than a marketing claim about it.
If a provider can't produce any of these on request, treat its rankings as opinion rather than evidence.
How we actually use these signals day to day
At Ontherice, triage happens the same way we'd recommend to any reader: a signal earns a watchlist slot only after it clears breadth and velocity checks, not on first sighting. One recent example, kept deliberately vague to protect the underlying client work, involved a product-attribute phrase that surfaced across two AI assistants roughly six weeks before a competitor caught it in traditional search data.
That gap is the whole argument for treating this as infrastructure, not a novelty. If you want to see it in action, running a live query yourself, and comparing what it surfaces against your own market read, tells you more in ten minutes than any pitch deck. We'd genuinely like to know where it's wrong.
— Aidil
Putting github trend signals to work with Ontherice
Ontherice gives you the tooling to move from "we noticed something" to "here's the evidence" without building a data pipeline yourself. The RankingsGeneratorEngine produces sector rankings you can slice by category, while AIOpportunities surfaces emerging signal cards before they're mainstream enough for a traditional research report to catch them.
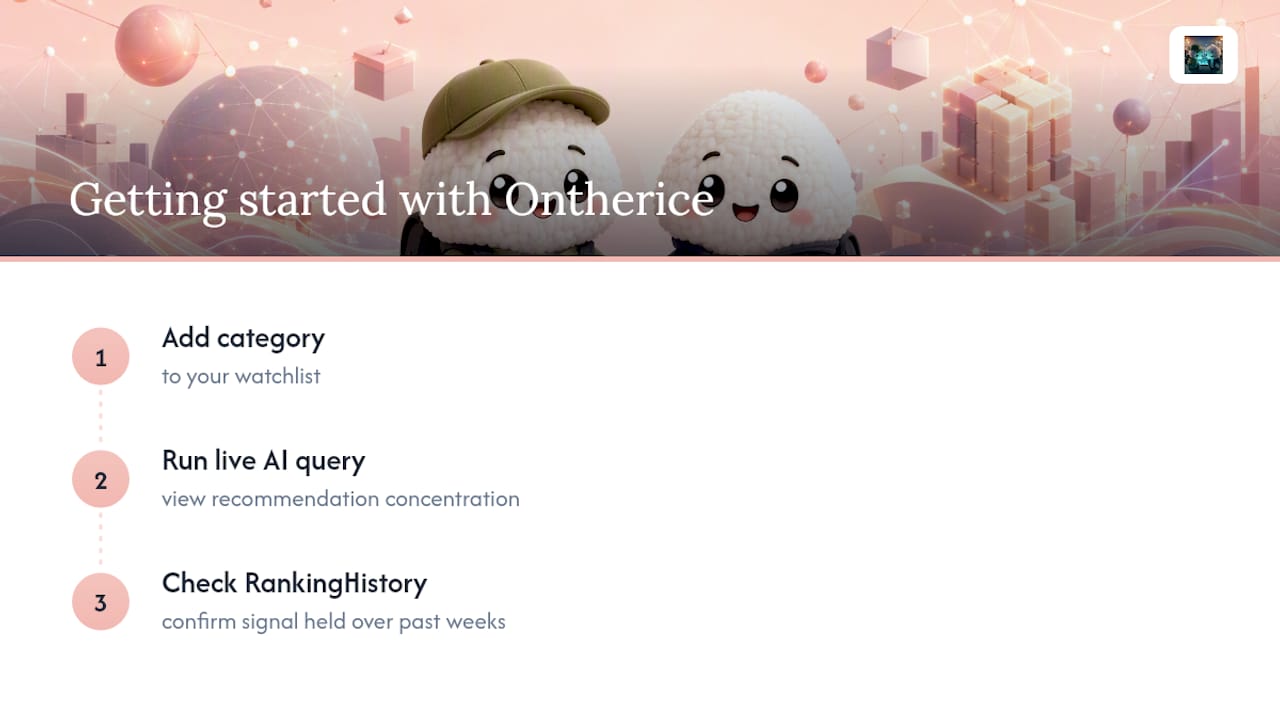
Getting started takes three steps: add a category to your watchlist, run a live AI query against it to see current recommendation concentration, then check RankingHistory to see whether the signal has held over the past several weeks or was a one-off spike. That timestamped record is what turns a hunch into something you can put in front of an investment committee. For a broader technical view of how signal pipelines get built, AiTools walks through the underlying methods, and teams pulling in external data streams like video transcripts as part of a wider detection pipeline may find the YouTube Transcript API guide a useful technical reference.
Start with one category that matters to your business, run the query, and see what surfaces on the AIOpportunities feed this week.
Sources
The arXiv nowcasting study grounds the winner-picking asymmetry discussed above. UltraScout's practitioner guide supports the 4 to 12 week lead-time claim. Redpanda's streaming data engineering notes and Swissquote's analysis of AI market blind spots inform the technical limitations section.
- Can agentic AI nowcast stock returns? (arXiv) — 2026-01-17
- How to Predict Market Trends with AI 2026: A Practical Guide | UltraScout AI
- Real-time AI and streaming data (Redpanda blog)